---
title: "My take on subagents, forks and collapsing context"
description: "Why I want agents to summarize finished work, keep the full transcript reachable, and inherit context when they delegate."
date: 2026-10-12
url: https://arthur.place/subagents-forks-collapsing-context
image:
src: "https://arthur.place/_astro/subagents-forks-collapsing-context.C7mLp58R_Zpwv2H.jpeg"
alt: "A red thread winds through a landscape of papers, maps, and filing drawers."
---
# My take on subagents, forks and collapsing context
When I ask an agent to make a project build, it may spend several turns reading errors,
trying fixes, and running the build again. Once it passes, I want it to continue with the
feature. But every failed run is still in its context.
Delegating the build to a subagent keeps the logs out of the main conversation, but
introduces a problem I keep seeing in subagent prompts: the child gets the task without
enough of what the parent already knows. It has to rediscover the Node version, a pinned
dependency, or a constraint I gave earlier.
I want the agent to do the build work with its existing context, then replace those turns
with a short note: what changed, whether the build passed, and what is still unchecked.
The full transcript should remain available if it needs a detail later. I call that
operation a **fold**, and the span it summarizes an **episode**. Figure 1 draws the build
loop as a tangent off the main task.
Figure 1: the build loop goes off on a tangent, then folds into one note with handle
b2e4. The full tangent stays archived and reachable.
I used to approximate this by asking the main agent to maintain a Markdown file with its
context and reasoning, then passing the path to every subagent. Rewriting the file as the
work progressed helped more than continually appending to it. But I still had to ask for
updates, and anything removed from the file was hard to find again. I want the harness to
manage those updates and keep each note connected to the work behind it.
I have built an experimental version for pi,
[pi-episodes](https://github.com/arthurfiorette/pi-episodes). The diagrams and cost
estimates use hypothetical runs. I do not yet know whether folding improves task outcomes.
## Fold finished work before the context fills
Suppose an agent is adding a feature: it explores the project, writes a query, fixes the
build, then wires up the frontend.
With ordinary compaction, the build logs stay between the query and the frontend work
until the context window fills. The harness then summarizes the conversation, sometimes
retaining recent turns verbatim. OpenCode, for example, has a setting for how many recent
tokens to keep beside the summary[^1]. The timing depends on context size, even if the
build work finished much earlier.
With a subagent, the logs never enter the parent's context. This also preserves the
parent's prompt-cache prefix. The tradeoff is the handoff: a fresh child knows only what
its instructions and task prompt include. Some harnesses let the parent resume past
subagents to ask follow-up questions, but the parent still has to recognize that it needs
to. It also has to delegate before seeing how long the work will take. If a quick build
turns into seven long turns inline, delegation cannot remove those turns afterward.
With a fold, the agent runs the build inline and summarizes it once it finishes. It keeps
its existing context while doing the work, then carries the result into the frontend task.
It does not need to predict whether the build will be long enough to justify a subagent.
Context size during the same build loop. Ordinary compaction retains the logs until the
window fills. A subagent keeps them in a separate context. Folding removes them from the
main context after the build passes and retains an archived copy.
Prompt caching reduces the cost of carrying old logs, but those tokens still occupy the
context window, and the model still attends to them on every turn. Folding changes what
the model receives on later turns. With `B` for the context before the build, `E` for the
build episode, and `A` for the work afterward:
```
today: B + E + A
proposed: B + fold(E) + A
```
I expect the smaller context to be sufficient for the remaining work, and possibly to help
the model avoid obsolete guesses. That needs testing: changing the context also changes
the steps the agent takes, so the comparison has to measure task outcomes.
## How a fold changes the conversation
After the build passes, the agent identifies the first turn of the build loop and writes a
note:
```
fold(since: "t4", note: "...") -> "b2e4"
```
The harness archives the span under the handle `b2e4`, replaces it in the active context
with the note and handle, and preserves any user messages from that span. The conversation
before `t4` stays unchanged. It can remain a cache hit if the provider still has a
matching entry at that position[^2].
The archive belongs to this session. It stores the original transcript, unlike memory
files or AGENTS.md, which contain selected information intended for reuse across sessions.
### Preserve the constraints on each result
I use the same note template for each fold:
- changed (files, config, external state)
- learned, including caveats
- decided and rejected
- open items
- where to look if this proves insufficient
This resembles existing compaction prompts. OpenCode's already asks for decisions, work
state, next steps, relevant files, and exact paths and error strings[^1]. I am proposing
to use that kind of summary over a smaller span, earlier in the session.
The difficult part is preserving conditions that a later change might violate. Suppose the
agent writes a job-claim query using `FOR UPDATE SKIP LOCKED`. The selection and claim
must happen in the same transaction so the row lock lasts until the claim is recorded. A
note saying only "the claim query works" omits that requirement. If the agent later moves
the selection outside the transaction, two workers could claim the same job.
The archive may contain the explanation, but the note gives the agent no reason to look
for it. "The claim query works; keep selection and claim in the same transaction" gives
the later step the constraint it needs.
Most raw material for the note is already in the episode, in the agent's own messages
after each tool result: what the output meant, what to try next. Those messages need
editing before they can stand alone. Some refer to output that will no longer be visible;
others contain guesses rejected later. The note should retain the supported conclusions
and quote exact error strings or paths where needed.
From a 400-line build log plus mid-episode replies to a five-line note: changed,
learned, rejected, open, where. The note is written after the loop so it can account for
guesses rejected in later turns.
The loop runs inline, then folds at t4 into one block: the note with handle b2e4 plus
the user's message verbatim. A second pass shows why the transaction caveat must stay in
the note.
### Choosing which turns to fold
"Until the build passes" is easy to specify beforehand. Which files the agent will read,
which earlier decisions it will need, and how long it will take are harder to predict.
Folding lets the agent choose the span after it has that information.
It must identify both the end of the activity and its start. In this example, the start is
the first build run, not the query written before it. The harness stamps turns with stable
IDs, so the agent can select an existing mark. Choosing badly could summarize unrelated
work or leave half the logs in context. The archive makes the original turns recoverable,
but recovery still takes time and may not happen before a mistake.
A passing build gives the agent a useful point to consider folding. It still has to ask
whether the note preserves enough information for the next step. For open-ended work,
where the question keeps changing, I would often leave the episode open. Even a good
decision about timing cannot establish what the agent will need twenty turns later.
## Where the idea came from
When I write a query, I read the ORM documentation, the schema, and the details of the
table. Afterward I keep the query and perhaps a reminder that it only works inside a
transaction. I can look up the documentation again. A teacher finishing a tangent and
asking "where was I?" was the example that first made me think agents could do something
similar.
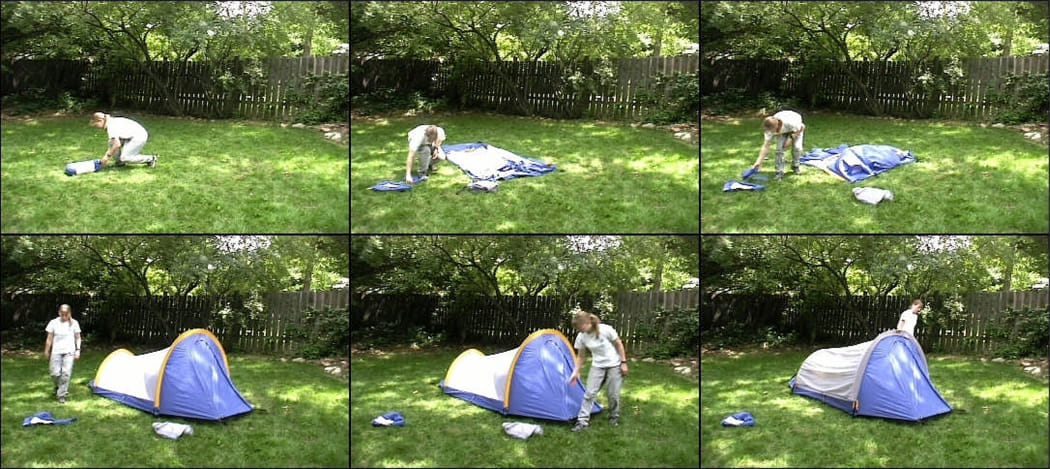
The closest research I found is Event Segmentation Theory: Zacks and Swallow, [_Event
Segmentation_][zs2007], and Kurby and Zacks, [_Segmentation in the perception and memory
of events_][kz2008]. They describe how people divide continuous activity into events and
update their working model when predictions stop matching what happens. Agreed boundaries
often coincide with completed subgoals.
Six coarse boundaries viewers agreed on while watching someone pitch a tent: put it
down, spread it out, insert the front pole, stake the ends, stake the sides, attach
the rain fly. Reproduced for commentary from Zacks and Swallow (2007).
Kurby and Zacks also cite studies where people who identified finer event boundaries
recalled more detail. That led me to consider summarizing smaller spans of work.
Altmann and Trafton's [_Memory for goals_][at2002] gave me another design question: what
will remind the agent to return to unfinished work? Their model emphasizes cues associated
with a goal before it is suspended. For my design, that suggests recording specific open
items before folding.
These studies helped me develop the design, but concern human perception and memory.
Asking a model to select and summarize its own work is a separate experiment.
## Let delegated work inherit the parent's context
Folding handles work that ran inline. If I want to delegate the build instead, the child
still needs the relevant things the parent learned. Writing a complete handoff can be
difficult when those details are scattered across hundreds of messages.
For work that continues the parent's task, `fork` gives the child a copy of the parent's
current context:
```
fork(task) -> result, handle
```
The harness copies the parent's message array, closes the open tool call in the copy with
the task as its result, and runs the child to completion. It returns the final message and
a handle to the child's transcript. The parent still specifies the task, but does not have
to reconstruct the background in a handoff prompt. The unchanged prefix is eligible for
cache reuse while a matching entry remains available.
That larger prefix is re-read on every turn, so I wanted to see what it costs over a whole
loop. The comparison below assumes:
- a 100K-token parent prefix and a 15K-token fresh subagent system prompt;
- 30 turns adding 150K tokens, spread roughly evenly across the loop;
- cached reads at 0.1x the fresh input price and writes at 1.25x;
- a fresh child re-reading 30K tokens of material the parent already read, then carrying
that material through the loop.
The token columns apply those rates. For example, reading the fork's 100K prefix from
cache 30 times costs the equivalent of 300K fresh input tokens. The comparison omits each
child's initial prefix write and output-token costs. It assumes the same number of turns
and amount of build output for both children.
|cost|rate|fork|fresh subagent|
|-|-|-|-|
|prefix, read from cache on every turn|0.1x|300K|45K|
|loop growth, written once|1.25x|188K|188K|
|loop growth, read from cache as it grows|0.1x|225K|225K|
|re-reading what the parent had read|1.25x once, then 0.1x|0|~125K|
|total, in fresh-token equivalents||~713K|~583K|
|in dollars, at $3 per million fresh tokens||~$2.14|~$1.75|
In this example, the fork's input cost is about 1.2x the fresh child's, or 1.6x if the
child needs no repeated reading. Comparing only their prefixes would suggest a gap of
nearly 7x and miss the build output both children carry. Longer parent contexts increase
the premium; cheaper cached reads reduce it[^2]. An expired cache adds a prefix write.
The fork also inherits the parent's wrong guesses. Giving it the entire conversation could
recreate the problem that made subagents useful.
The package therefore forks the parent's current view after earlier folds. If the query
work has already been summarized, the child receives that note instead of the query's full
history. This can remove rejected guesses, though a mistaken conclusion in the note will
still be inherited. Open episodes remain in full.
For example, if earlier folds reduce the assumed prefix from 100K to 40K, the fork's total
in the table drops to about 533K fresh-token equivalents. That is below the fresh child in
this example, before including the cost of creating those notes. For a short lookup with
little dependence on prior work, I would still use a fresh child.
Both fork and fold leave a result in the main conversation and a transcript the parent can
revisit. The difference is when the agent chooses: a fork starts a separate thread before
the work, while a fold selects completed turns afterward. Several forks can run at once,
but their file edits must be coordinated because the working tree is shared. Whether the
parent waits or continues interacting with the user is a scheduling choice for the
harness.
Fork decides before the loop and runs it on a copy of the parent. Fold runs it inline
and decides after, picking the start. Both end with the same main line and archive.
Costs use the assumptions from the table above.
### Give reviewers the requirements without the parent's conclusions
I want a reviewer to check my work without first reading my explanation of why it is
correct. A fork would give it exactly that explanation, along with the rest of the
conversation.
For review, I would use a separate agent with the user's requirements, the diff, and
access to the relevant code. It needs the original constraints to find violations of them.
It does not need the implementing agent's conclusions. I expect this to reduce agreement
caused by inheriting those conclusions, though using the same model still leaves shared
blind spots.
The package provides `fork`; independent review requires a separate subagent tool. Its
prompt explains how to brief one if the harness has it.
A fork inherits the parent's view. In this example, a reviewer given the requirements
and diff finds the transaction bug; one given the parent's reasoning repeats its
conclusion.
## Retrieve details the note left out
When the agent needs an exact error or the reason an approach was rejected, it can
retrieve that information from the archive with two tools:
```
recall(query) -> matching lines, each with the thread it came from
ask(handle, question) -> one answer from that thread
```
`recall` searches the archive without a model call. The package uses exact and regex
matching for strings such as error codes, and BM25+ ranking for less exact queries. The
search includes tool outputs, agent messages, and reasoning where the provider returns it.
Pi's compaction remains available when the context fills, and `recall` also searches the
turns it summarized. Searching first avoids an inference call, but the agent still needs
to know roughly what to look for.
`ask` answers questions such as why the agent chose one fix over another. It loads the
archived conversation (`B + E`) with the question and returns an answer to the main agent.
The archived messages stay outside the main context. The request retains the original tool
definitions so that they do not break the cached prefix, but executes no tools. To read
current files or run another check, the agent needs a fork or its usual tools.
An `ask` re-reads `B + E`, using any matching cache entry that is still available[^2]. For
older work, I budget for a fresh read. Whether that costs less than repeating the
investigation depends on the thread size and the work it saves.
recall("TS2322") returns matching lines from b2e4 with no inference. ask("b2e4", ...)
reloads that thread off the main line and returns one answer. Only the answer enters the
main line.
A fork can also fold its own turns, producing nested archive entries, but cannot fold the
parent's inherited context. On a single conversation line, a fold cannot reach behind an
earlier note. `recall` searches across all the spans and identifies the source thread for
each match; `ask` accepts any handle, including one created inside a fork.
The case I have least evidence for is when the agent does not realize it needs to look
back. In the query example, a note missing the transaction constraint might never prompt a
lookup. The package's prompt asks for caveats in notes and lookups before guessing about
earlier work. It also records which files each span touched. When a later `read`, `edit`,
or `write` touches one again, the tool result points to related archived work. Shell
commands do not trigger that cue.
There are further retrieval experiments I want to try:
- Index symbols as well as files to identify related work more precisely.
- Match recent context against the archive and suggest relevant threads, then measure
whether those suggestions help or distract the agent.
- Use failed tasks and their archive lookups to identify missing constraints in notes.
Those cases could become training examples. A lookup for an exact error string, by
contrast, may be a reasonable way to keep a note short.
In an interactive session I can also intervene when something looks wrong, but that does
not help an unattended run.
An archived answer reflects the files as they were during that episode. If those files
have changed, its explanation may no longer apply. While working-tree snapshots are
available, `recall` and `ask` report which files changed since the thread was archived.
The snapshots last only for the session, so that check is unavailable after a restart.
## What the harness must store and preserve
The four tools use the following data model:
|name|what it is|
|-|-|
|log|one append-only message list per thread: the main line and every fork|
|view|what the model sees: the main log with folded spans replaced by their notes|
|archive|the logs of folded spans and finished forks, with an index of the files each touched|
|handle|the ID of an archived span|
Several implementation details matter for preserving the conversation:
- The harness stamps user messages and tool results when it saves them. The model uses
those visible IDs in `since`. Adding stamps later would change already-cached text.
- A fold keeps tool calls paired with their results and cannot reach behind an earlier
note or compaction summary.
- The prompt asks for the note template above, and the harness appends the archive handle.
- User messages keep their original wording and stamps, so a correction made during the
build still reads as a correction from that turn. Pastes over 4,000 characters are
shortened with a pointer to the full text.
- Working-tree snapshots supply the file diff for a main-thread fold. Without snapshots,
the package lists paths touched by file tools instead. A fork reports one diff for its
whole run, rather than a separate diff for each fold inside it.
- Removing messages from the model's view leaves their saved transcripts intact.
- After a fold, the package reminds the agent about open items on the next user prompt.
- `/fold` lets the user choose the starting turn and asks the agent to write the note.
Manual folding is my baseline: I decide when to fold and where the span starts, then
inspect the note the agent writes. That gives me a way to test note quality separately
from the model's ability to choose a span. Automatic folding has to be useful enough to
justify handing over that choice.
## Preserve cache entries at fold and fork points
The cost estimates depend on reusing cached prefixes. Anthropic and newer OpenAI models
support automatic placement of cache breakpoints and explicit placement of up to four per
request[^2]. A turn ID such as `t4` only marks a log position. To reuse the prefix at that
point, the provider also needs an eligible cache entry there.
|operation|what changes|cache|
|-|-|-|
|append|add a tool result or other message|reuse an available prefix entry and process the new tail|
|fork|copy the parent's view and add the task|reuse an available parent-prefix entry; each child processes its own tail|
|fold|replace a span with its note|reuse an available entry before the changed span; process the remaining context and note|
|compaction|replace older conversation with a summary|process the rewritten portion; unchanged earlier content may still be cached|
|ask|load the archived context and add a question|reuse an available entry for that context, or process whatever is no longer cached|
Keeping the system prompt and tool definitions stable allows these operations to share
cached prefixes. Anthropic places tools before the system prompt and messages, so editing
a tool definition changes the prefix for everything after it. OpenAI also lists tool
definitions among settings that affect cache matching. Fork instructions belong in the new
task message; per-request information belongs near the end of the request.
The harder problem is choosing where to cache before the agent knows which turns it will
fold. On Anthropic, pi-episodes places an extra breakpoint on the newest fold note or
stamped user message. The actual episode may start several turns after that anchor. If a
later fold preserves messages between that anchor and its chosen start, those messages may
still need processing again. The package's measurement plan includes that cost.
An unchanged prefix alone does not guarantee a cache hit. The provider must have a
matching entry, and a prefix shared by several simultaneous forks may need to be written
before any of them can reuse it. I want to measure actual hits at fold and fork points
rather than infer savings from the conversation layout.
Anthropic defaults to five minutes and offers an hour at a higher write price. Newer
OpenAI models default to thirty minutes; some older models support retention up to a
day[^2]. Long tool calls or a pause in the session can outlast those entries. Archive
lookups are especially likely to need a fresh read, so their cost needs to be measured
separately from the active build loop.
## Try the implementation in pi
I built this as a package for [pi](https://github.com/earendil-works/pi):
[pi-episodes](https://github.com/arthurfiorette/pi-episodes).
```sh
pi install npm:pi-episodes
```
In interactive pi, `/fold` shows a list of turns so you can pick where the span starts;
`/fold t13` selects that turn directly. The agent then writes the note. Without an
interactive picker, plain `/fold` lets the agent choose the span.
To try it, fold after a real build loop, then give the agent a task that depends on a
detail from that loop. Check whether the note preserved the detail or the agent retrieved
it before acting.
I am comparing context size, retrieval cost, and mistakes caused by missing information.
Retaining the archive lets a note omit details that are unlikely to matter again, but a
shorter note is not an improvement if it causes enough extra lookups or worse results. The
questions I am testing are:
- whether the model notices an episode ended and picks its start unprompted
- whether its notes keep caveats, or fail the "query works" way
- whether it goes back when it should, and whether the file-touch cue helps or adds noise
- whether a fork anchors on the parent's wrong guesses more than a fresh subagent
- whether the smaller context improves task outcomes compared with keeping the full logs
The repository has a measurement plan for those questions. I am working through it and
will report the results. If you try the package, I would like examples where a note kept
the right detail, omitted something important, or led the agent back to the archive.
[zs2007]: https://pmc.ncbi.nlm.nih.gov/articles/PMC3314399/
[kz2008]: https://www.cell.com/trends/cognitive-sciences/fulltext/S1364-6613(07)00331-2
[at2002]:
http://act-r.psy.cmu.edu/wordpress/wp-content/uploads/2012/12/6ema_jgt_2002_a.pdf
[^1]:
OpenCode's
[compaction](https://github.com/anomalyco/opencode/blob/dev/packages/core/src/session/compaction.ts)
has a `keep` setting, "tokens of recent conversation kept verbatim beside the
summary", and its summary template asks for objective, requirements, decisions, work
state (completed, active, blocked), next move, relevant files and important context,
with a rule to preserve exact file paths, symbols, commands and error strings.
[^2]:
Sources:
[Anthropic](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) and
[OpenAI](https://platform.openai.com/docs/guides/prompt-caching) prompt caching docs.
The cost table assumes 0.1x reads and 1.25x writes, matching Anthropic's standard
five-minute pricing and most GPT-5.6-and-later models.